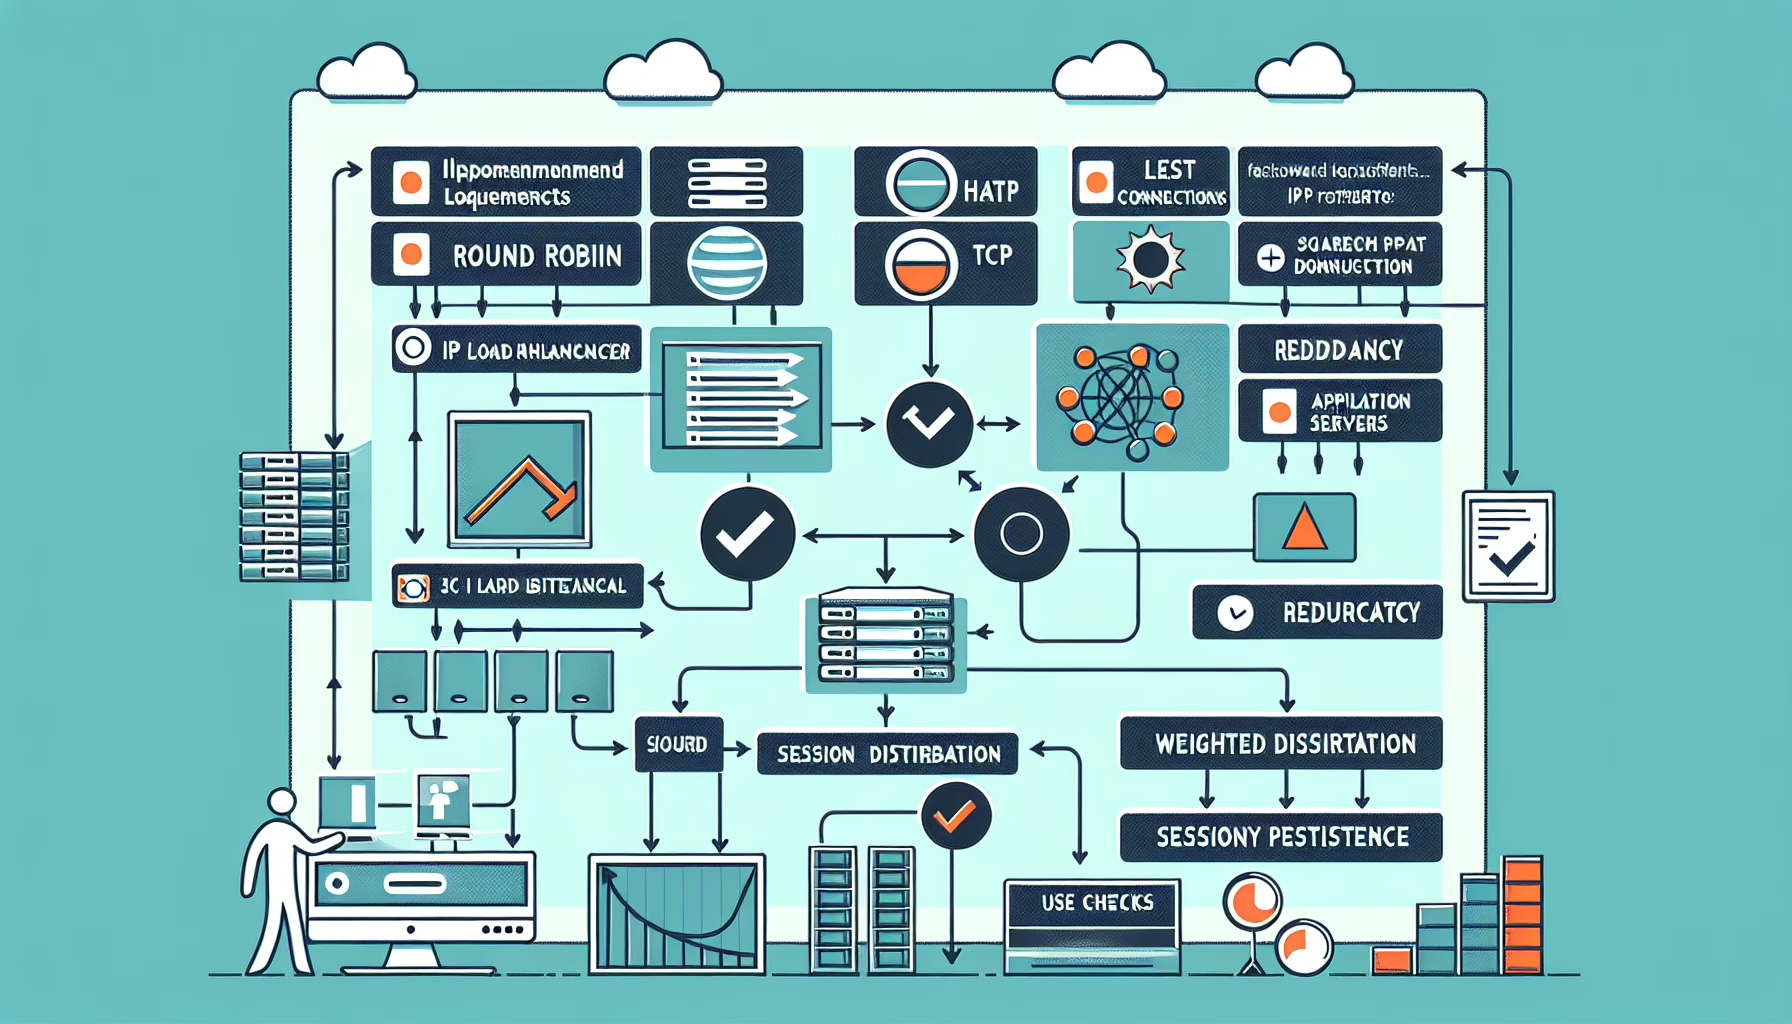
Load balancing application servers gives you high availability, scalability, and better performance. Here’s how to set it up:
1. Define Requirements
- Traffic type: HTTP(S), TCP, UDP, or other protocols
- Number of application servers to balance across
- Redundancy: failover capabilities for server or load balancer failure
- Scalability: anticipate growth and ensure the design scales easily
- Persistence needs: determine if session persistence (sticky sessions) is required
2. Choose a Load Balancing Algorithm
Pick an algorithm based on your application’s behavior:
- Round Robin: distributes requests sequentially across servers
- Least Connections: sends traffic to the server with the fewest active connections
- IP Hash: routes based on the client’s IP address
- Weighted Distribution: assigns weights based on server capacity or performance
Health checks aren’t an algorithm—they’re a required mechanism to verify servers are healthy before routing traffic to them.
3. Select a Load Balancer Type
Match the load balancer to your infrastructure:
- Hardware load balancer: dedicated appliance (F5, Citrix ADC)
- Software load balancer: open-source tools (HAProxy, Nginx, Apache, Envoy)
- Cloud-based load balancer: AWS ELB, Azure Load Balancer, Google Cloud Load Balancer
- Kubernetes Ingress Controller: for containerized workloads (Nginx Ingress, Traefik)
4. Deploy the Load Balancer
- Hardware/Software: install and configure on dedicated hardware or VMs
- Cloud: provision a load balancer service from your provider
- Kubernetes: deploy an ingress controller or a
LoadBalancertype Service
5. Configure the Load Balancer
- Back-end server pool: define all application servers behind the load balancer
- Health checks: configure periodic checks (e.g., HTTP 200 response) to verify servers are operational
- SSL/TLS termination: terminate HTTPS at the load balancer if needed
- Session persistence: configure sticky sessions if your application requires them
- Routing rules: define traffic routing (URL-based, host-based, etc.)
6. DNS Configuration
- Point your application domain or subdomain to the load balancer’s IP address
- Use a CNAME record for cloud-based load balancers when applicable
7. Monitor & Optimize
- Monitoring: enable logging and metrics to track traffic and server health. Use Prometheus, Grafana, or built-in dashboards
- Auto-scaling: on cloud or Kubernetes, configure auto-scaling for backend servers
- Performance testing: regularly test the load balancer under high traffic
8. Implement Redundancy
- Deploy multiple load balancers in active-active or active-passive configuration
- Use VRRP (Virtual Router Redundancy Protocol) or cloud-native failover for high availability
Example: Kubernetes Applications
- Deploy an ingress controller (e.g., Nginx)
- Define ingress rules for routing traffic to specific services
- Use
Horizontal Pod Autoscaler (HPA)to scale application pods dynamically
Example: Traditional Web Servers
- Deploy HAProxy or Nginx
- Configure upstream servers in the configuration file
- Use
Keepalivedfor high availability between load balancers

Ali YAZICI is a Senior IT Infrastructure Manager with 15+ years of enterprise experience. While a recognized expert in datacenter architecture, multi-cloud environments, storage, and advanced data protection and Commvault automation , his current focus is on next-generation datacenter technologies, including NVIDIA GPU architecture, high-performance server virtualization, and implementing AI-driven tools. He shares his practical, hands-on experience and combination of his personal field notes and “Expert-Driven AI.” he use AI tools as an assistant to structure drafts, which he then heavily edit, fact-check, and infuse with my own practical experience, original screenshots , and “in-the-trenches” insights that only a human expert can provide.
If you found this content valuable, [support this ad-free work with a coffee]. Connect with him on [LinkedIn].
Related Posts: